Secure Custom Knowledge Chatbot
A white-label enterprise chatbot platform solving the core problem of generic AI: inability to answer company-specific questions. Built on Graph RAG architecture with an adaptive security layer, it serves as a secure internal knowledge assistant or customer-facing support agent.
// Key Challenges
- Hallucination Risk: Generic LLMs answer questions outside their training data with confident but fabricated responses, unacceptable for enterprise use.
- Prompt Injection Attacks: Bad actors attempt to override system instructions through crafted user inputs to extract confidential knowledge.
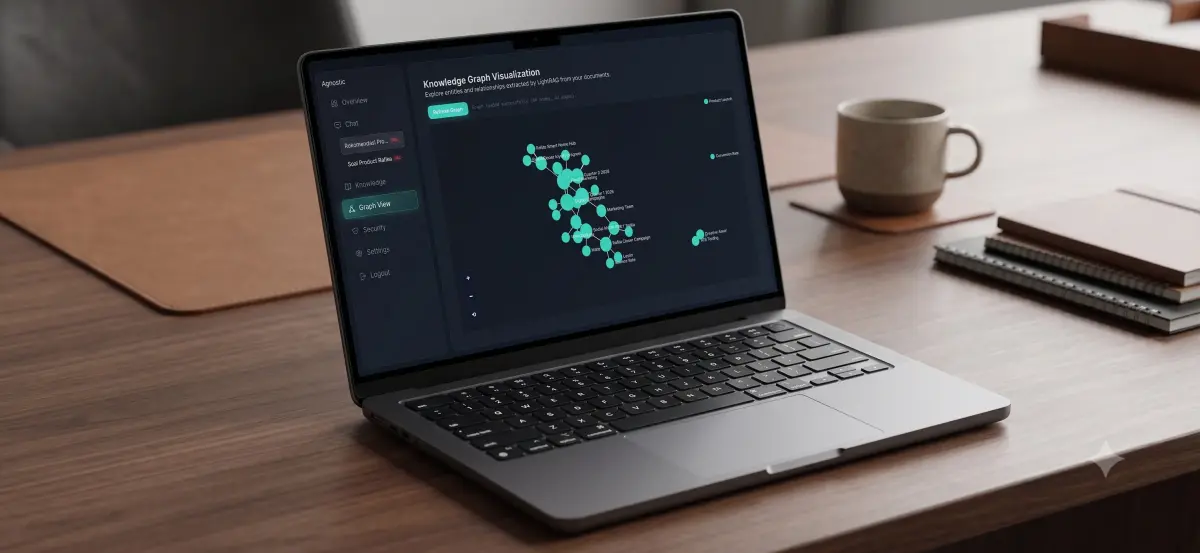
- Context Fragmentation: Standard RAG with flat vector search loses relational context between documents, degrading answer quality.
- Integration Friction: Organizations needed chatbot capabilities embedded in their existing tools, not a standalone platform requiring staff migration.
// Approach & Solutions
1. Graph RAG Knowledge Architecture
Documents are parsed into entity-relationship graphs, preserving semantic connections between concepts. This enables multi-hop reasoning across documents that flat vector search cannot achieve.
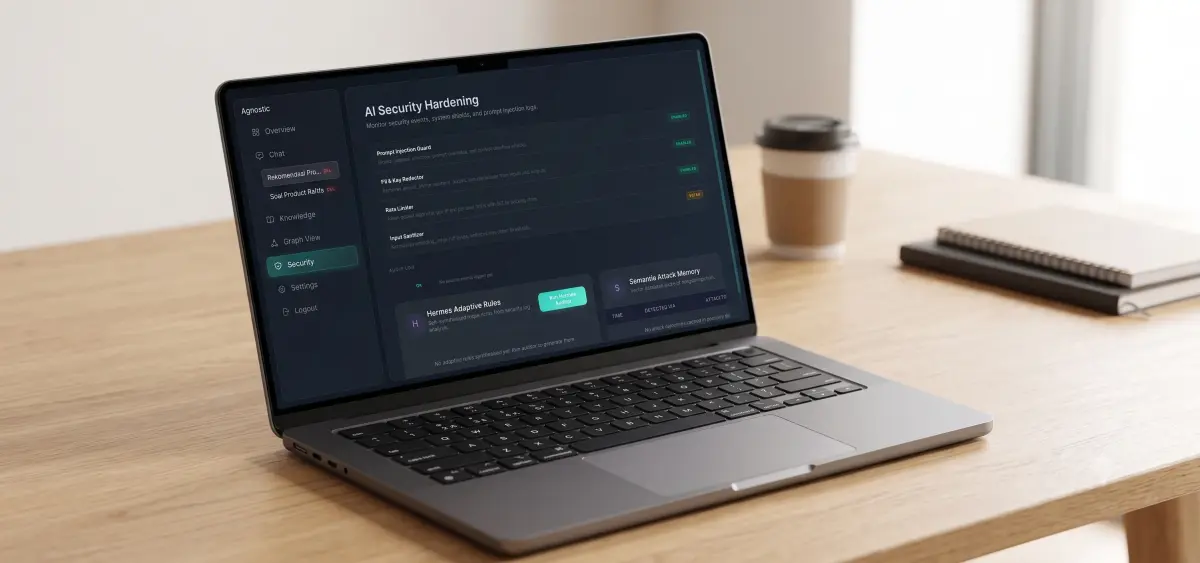
2. Adaptive Prompt Injection Shield
A multi-layer detection system combining rule-based pattern matching with a behavioral model that learns from flagged injection attempts, improving detection accuracy over time without retraining the base LLM.
3. Dual-Mode API + UI Access
Organizations receive a scoped API key with rate limiting and per-key knowledge base access controls, enabling seamless embedding into existing CRMs, intranets, or mobile apps.
// Tech Stack
| Technology | Reason |
|---|---|
| Graph RAG (Knowledge Graph + Vector Search) | Combines graph traversal for relational context with vector similarity for semantic relevance, achieving answer precision that standard RAG cannot match on complex multi-document queries. |
| LLM via OpenRouter | Model-agnostic routing enables switching between GPT-4, Claude, or open-source models based on cost/performance requirements without changing application code. |
| FastAPI | Async request handling for simultaneous multi-user chat sessions with sub-100ms API response times for non-LLM operations. |
// Results & Business Impact
- ~0% - Hallucination Rate (Answers grounded strictly to uploaded knowledge base, not general LLM training)
- 99%+ - Prompt Injection Detection (Adaptive model catches novel injection patterns missed by static rules)
- API-ready - Integration Capability (Embeddable into any existing platform via scoped API keys in under 30 minutes)
- Live - Production Status (Actively serving clients at chat.zeroman.my.id)
// Project Gallery